Jul 20, 2026
Data validation techniques in server-side tagging
Written by
Ivanna Holubovska
Updated Oct 14, 2026 comments
Key takeaways
- Data validation is the process of confirming that collected data is accurate, complete, and correctly formatted before it reaches storage, analytics, or advertising systems – errors that slip through at this stage tend to compound further down the pipeline.
- The main validation types, such as format, completeness, range, uniqueness, consistency, and integrity checks, serve different purposes and work best when combined into a layered strategy rather than applied individually.
- Validation should happen at every stage of the data flow: at the source, on the server, and at the point of transfer to destination platforms; no single checkpoint is sufficient enough on its own.
- Server-side Google Tag Manager acts as a natural middleware layer for running server side validations, catching anything that passed the client-side checks and allowing data to be corrected before it feeds reporting or ad platforms.
- Automating verification processes, establishing clear data specifications, and conducting regular testing are essential best practices for maintaining a scalable and adaptable tracking setup.
- Properly validated data has a direct business impact: it improves attribution accuracy, supports GDPR and CCPA compliance, strengthens ad platform match rates, and reduces operational overhead from broken tags and misfired events.
Companies running server-side tracking collect and process customer data around the clock, often with little to no manual review at the point of collection. That shifts the entire responsibility for data quality onto the schemas, field rules, and validation checks set up in advance. When those aren't in place, bad data enters the system unchecked: it generates costs in cleaning, transformation, and storage. And the errors it carries compound over time, appearing later as broken attribution, inflated event counts, or misfired automations. This article covers the data validation testing techniques used in server-side tracking, the most common errors to watch out for, and what a reliable validation setup looks like in practice.
What is data validation?
Data validation is the systematic process of verifying the accuracy, structure, and quality of incoming information before it is processed, stored, or transmitted. In server-side tracking, these checks help confirm that incoming events and their parameters follow the expected formats and business rules before they are stored, analyzed, or forwarded to other systems. This is especially important in automated data collection, where errors can pass through without manual review and create reporting problems or require additional effort to clean and transform the data. Effective customer data validation therefore helps maintain trustworthy tracking data and prevents issues from propagating further through the server-side workflow.
Data validation techniques
Several basic data validation techniques help maintain data quality in the server-side tracking process. These checks can be combined into a broader validation strategy depending on the data source, destination, and business requirements.
Format validation
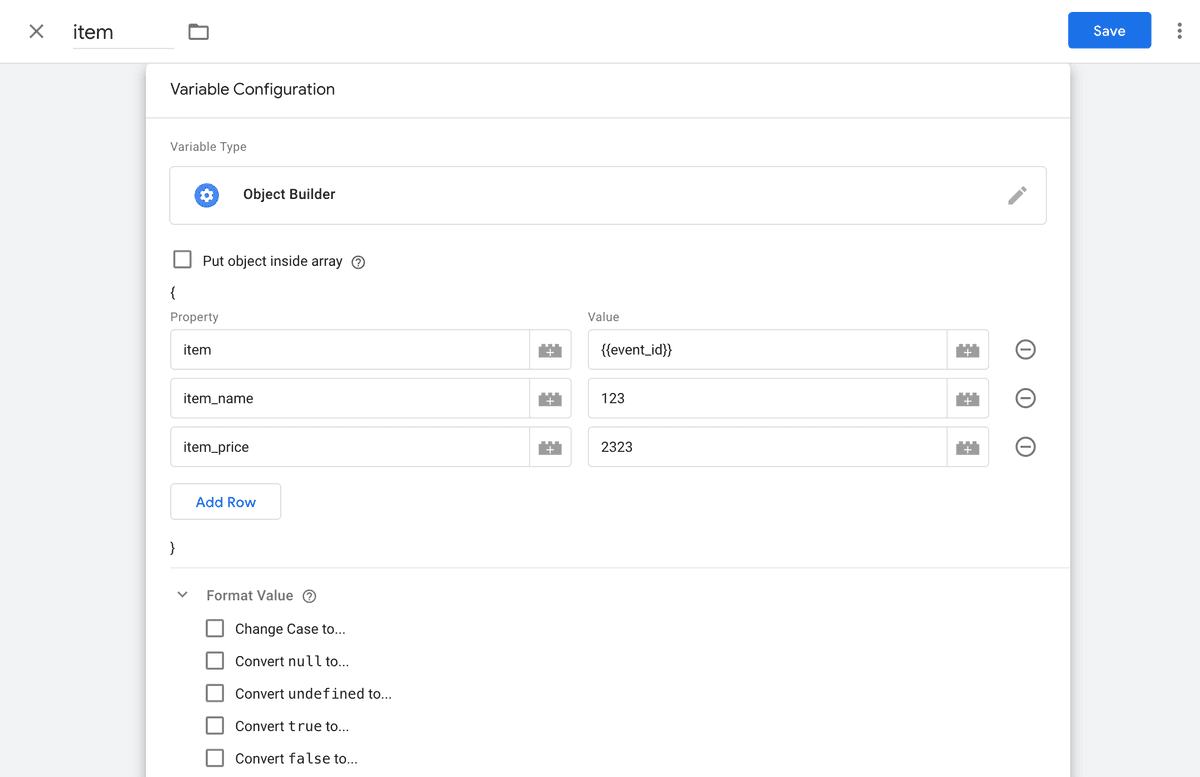
Format validation checks whether data follows the structure expected by the receiving system. It is used to prevent invalid values from entering the tracking flow and causing processing or analytical errors. Consider a database of contacts where a person entered just a name or a random string instead of a valid email address. Without the "@" symbol and a domain, that record becomes useless to downstream systems. Incorrect formats can lead to failures in further processing or incorrect analytical conclusions. Format validation is equally important when data comes from different systems, since customer records, CRM events, and tracking payloads may use different representations of dates, identifiers, or other fields. Object Builder variable for sGTM, for example, provides some simple built-in tools for rudimentary validation, such as Format Value on all variables or regex matching inside triggers.
Completeness checks
Completeness checks verify that all required fields contain the information needed by the receiving system. For example, a tracking event may require a user ID, event time, or event type to be processed and interpreted correctly. If any of these mandatory fields is missing when the event is collected or sent to the server, analytics may lose important context, and subsequent systems may not have enough information to identify, attribute, or analyze the event correctly. This is why mandatory fields must be monitored carefully: their presence directly affects data quality and customer data validation.
Range validation
Range validation checks whether numerical data falls within acceptable bounds. The number of items in an order cannot be negative, and a user's age is unlikely to reach several hundred years – these constraints are obvious, but violations do occur and typically point to collection-side errors. Such checks help identify those inaccuracies before the data reaches the analysis stage. This approach is particularly valuable for transaction and eCommerce data, where fields such as quantities, prices, and discounts are expected to stay within reasonable business-defined limits.
Uniqueness validation
Uniqueness validation checks whether values that should identify individual records or events are actually unique. For example, each session or transaction must carry its own unique identifier. If the same transaction is processed twice, it will distort the accounting results. The Unique Event ID variable from Stape assigns a unique event ID across many tracking scenarios, which is essential for deduplication and for distinguishing between genuinely separate events and duplicate transmissions of the same event. This is particularly relevant when the same interaction can be picked up from multiple sources simultaneously.
Consistency checks
Consistency checks examine the relationships between data points rather than the values themselves. For example, the order completion date must always fall after the order creation date. The same logic applies when data from different systems is brought together in a tracking workflow: customer records, order details, and product information should follow consistent business rules. Catching these discrepancies early helps prevent serious logical errors in your reports.
Checking integrity constraints
Integrity checks confirm that data from different sources or database tables is correctly related. When data comes from different sources or is stored in several database tables, confirming that they relate correctly becomes critical. Integrity checking helps avoid disagreements and combines all information into a single, understandable picture. Implementing these constraints is one of the most reliable ways to maintain high data quality and integrity across your entire server-side tracking setup. From a data validation techniques integrity standpoint, this is the most complex check to configure, and the one that pays off most when your data comes from multiple touchpoints.
These principles also apply when data arrives from third-party sources or partners. Supplier data validation follows the same schema-matching and referential integrity rules to confirm that incoming feeds are consistent with your own records.
Common data validation errors and how to address them
Even in the best systems, errors in data validation occur from time to time. Here's what you should pay special attention to:
- No required parameters. Sometimes, important fields are simply not filled in at the data collection stage, which can become a serious problem for analytics. To avoid such situations, it is important to implement verification of mandatory fields at the stage of collecting or sending data to the server.
- Incorrect data format. For example, text may be entered in the "date of birth" field instead of a date, or a phone number may use an incorrect format. Using regular expressions can help prevent these mistakes at the beginning of the data flow.
- Typing errors. Sending text instead of a number, or vice versa, may seem minor, but in practice, such errors can cause serious system failures. To avoid this, the data must be checked automatically using scripts or built-in functions on the server.
- Duplicate data. Recording the same event multiple times distorts the measurement results. The solution is to introduce mechanisms for identifying and filtering duplicates at the data collection stage.
- Late update of data. Information changes over time, and analysts can be misled if it is not updated promptly. Having well-established verification processes and scheduling regular data updates is what keeps your tracking current.
How to use data validation with server-side tracking
For data to be truly reliable, building verification into all stages of processing is critical:
Validation at the data source level
Check the correctness of the information at the moment of its collection, be it a website, a mobile application, or a CRM system. That is why any solid server-side tagging implementation typically starts with a good dataLayer definition, documentation, and testing. This secures easier management down the pipeline by preventing errors from accumulating.
Source-level validation is particularly useful for on-site data validation, where information can be checked close to the point at which a user interaction occurs. It applies equally to data coming from mobile applications, CRM systems, and other collection points.
The goal is not to rely exclusively on source-level checks. Different sources may apply different rules, and some data may be modified or enriched later in the workflow. For this reason, validation should continue as the data moves through the server-side environment.
Create validation rules in the server environment
After the data arrives on the server, recheck it before sending it to analytics or advertising systems. This is one of the main strengths of a server-side Google Tag Manager. Running server side validations through GTM adds a second filter, which catches anything that slipped through the client layer. This middleware layer between the collector and storage makes it possible to validate and/or transform data before it reaches your reporting.
Setting up these strict server side validation rules often requires a strong technical foundation in data structures. If your internal team lacks the required resources, partnering with a specialized Google Tag Manager consultancy can help you define clear schemas and build custom middleware to guarantee accurate data transformation.
Error reporting
Set up data validation error notification systems to detect and correct problems in time. Use Stape's Logs and Monitoring features to stay informed about any anomalies or tracking issues as soon as they occur.
Error reporting should complement validation rather than replace it. A useful workflow identifies the failed check, shows where the problem occurred, and makes it easier to determine whether the issue originated at the source, on the server, or during transmission to another system.
Data validation best practices
For the data validation process to be really effective and maintain the quality of the data at a high level, it is worth following several essential recommendations:
1. Create clear data specifications.
Accurate and reliable data collection starts with clear rules for each field in your tracking setup. This includes verifying whether the field is mandatory, specifying the expected data type, the range of acceptable values, and the correct format. Many platforms, such as GA4, provide predefined schemas and formatting requirements. These systems differ in how strictly they enforce these rules; some may reject an entire event if even a single schema condition is violated.
2. Automate verification.
Manual verification is only suitable for small amounts of data. For medium and large volumes, implement scripts and automatic validation services. In a GTM environment, most of the time the tag templates (such as ones from Stape) will do the bulk of normalisation and verification of data input, nevertheless always check data-in and data-out in preview mode. Debug as needed
3. Implement multi-step verification.
Catching errors immediately during data collection is far better than detecting them in analytical reports. The check should be multi-level: on the client side, on the server, and when transferring to other systems. The balance between client, server, and destination validation can shift either way based on the particular situation. A server-side tagging approach with GTM provides a strong validation layer while still allowing you to implement additional custom checks when needed. These data validation testing techniques can be combined to test both individual fields and the complete data flow.
4. Test the verification system regularly.
Data validation must be a live process. It needs to be constantly improved, adapted to new business requirements, changes in data formats and changes in legislation. Regular testing should cover expected values as well as invalid, missing, duplicate, and incorrectly formatted data. This helps confirm that validation rules continue to work as the tracking setup evolves.
Why do companies need data validation?
Here's what your company gains when you implement proper data validation within your server-side tagging setup:
- Analytics accuracy. Validated data confirms that what you send to platforms like Google Analytics 4, Meta, or TikTok Ads is complete, correctly formatted, and aligned with platform expectations, eliminating discrepancies in event counts and attribution models. For TikTok server-side tracking, these checks help prevent errors in event names, parameters, and user data before events reach TikTok.
- Regulatory compliance. When working server-side, you're often handling sensitive user data, including emails, phone numbers, IP addresses. Validating this data before forwarding it supports compliance with privacy laws like GDPR, CCPA, and others.
- Customer understanding. With validated and deduplicated data flowing through your server container, you gain a clearer view of the customer journey. Whether it's aligning CRM data with on-site behavior or mapping user paths across devices, validated inputs help you create more personalized marketing campaigns.
- Marketing efficiency. Platforms like Meta and Google increasingly rely on server-side signals for optimization. If those signals are inaccurate or incomplete, your campaign performance suffers. Validating key fields like event names, parameters, and user identifiers (e.g.,
fbc,fbp,email_hash) leads to better match rates, more accurate conversion tracking, and a stronger return on ad spend. - Operational optimization. Valid data flowing through your server container reduces the need for manual debugging, minimizes broken automations, and helps you scale your setup across regions or brands with confidence. This leads to faster deployment of tags, easier QA, and fewer support escalations due to misfired or missing events.
Final words
A reliable validation process does not rest on a single check. Source-level controls, server-side rules, consistency and integrity constraints, duplicate detection, and regular testing each address a different failure point. Together, they form a validation strategy that holds up as the tracking setup scales and evolves.
Want to start using server-side tags?
Stape has lots of options! Click on Try for free to register and check all the benefits.
Try for freeRecommended for you
Sep 14, 2026
Blog
Who can benefit from Snapchat Ads (with examples)
Learn about Snapchat Ads: how they can be used in artistic spheres, politics, eCommerce, dropshipping spheres, and what benefits they can bring.
Jul 8, 2025
Comments